The typical ‘interface’ to probability distributions is the random variable.
Unlike a bare distribution, a random variable also keeps track of which concrete values can turn up as outcomes.
Let us recall the definition, now in the notation we will use from here on:
A reminder: if Ω and X are finite sets, every subset counts as an event, and then every such map is a random variable.
We will see later that we reach for the term random variable precisely when we are interested in expected values or higher moments.
Before we go on calculating, a question that is rarely asked and even more rarely answered: where in a dataset does the randomness actually come from? The short answer is that it is not in there at all. It is a decision we make.
A measurement that has already been taken is not random – the die has come to rest, the temperature has been read off, the row is sitting in the file. Collecting the data is a deterministic process too: a sensor writes down what it measures. Randomness is not something we find in the data; it is the language we use to talk about what we do not know about the data, or do not want to know. We treat the observed frequencies as if they were probabilities and draw conclusions from that model – so randomness is a modelling tool, not a natural substance.
All the same, there are three places where we do meet it quite concretely:
In the selection. When we draw a subset from the data we have – a sample, a mini-batch, a split into training and test data – the randomness is ours. We draw at random deliberately, so that the selection adds no structure of its own that we might later mistake for a result.
In sampling from a model. Drawing from a model distribution produces synthetic data. This randomness, too, is ours.
On the computer, not at all. Both of these run on a deterministic device that produces only pseudo-randomness: a sequence of numbers that looks random but is completely determined by its starting value, the seed. That is not a shortcoming; it is what makes analyses reproducible (see Programming with stochastics).
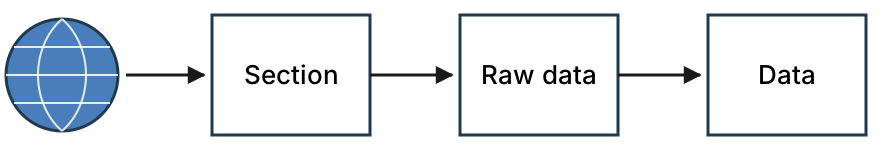
The path the data travel can be told in three pictures. First, data collection: a section of the world is chosen, raw data about it accumulate, and cleaning turns the raw data into the data we actually work with.
Figure 1:Data collection: from the world via a section and raw data to the data.
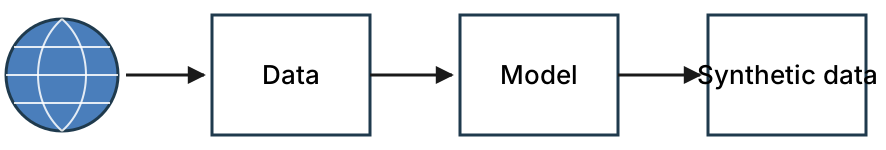
Then the modelling. A model is built from the data, and from the model, data can be generated in turn – synthetic data. Whether the model is any good comes down to whether its synthetic data resemble the real thing.
Figure 2:Modelling: from the data to the model and back to synthetic data.
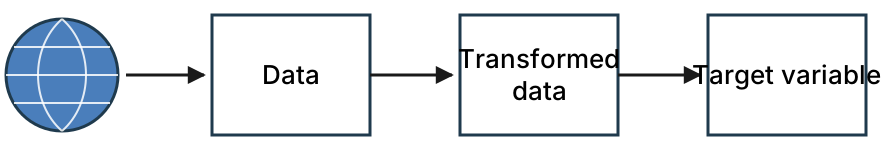
And finally the path to the target variable, which is what we were after all along: the data are transformed, and from the transformed data we compute the one number we wanted to know.
Figure 3:Analysis: from the data via transformed data to the target variable.
If all we are interested in is the distribution PX, we can forget about Ω:
the same distribution can be obtained from other sets Ω,
and from distributions on them that are not uniform.
In everyday work you usually calculate with probabilities not via the measure P on events but via a function p(x) that assigns each possible value x its probability directly. In the discrete case, which is what this chapter is about, this function is called the probability mass function; its continuous counterpart, the density, we will meet in a later chapter:
A distribution given in this way by p∈Δn is also called a categorical distribution; we meet it again in the chapter The most important discrete distributions, where we also work out its expected value and its variance. Its simplest case has a name of its own.
Geometrically, Δ2 is a line segment – the one joining the two vertices (1,0) and (0,1) – and π says where on this segment you are. Choosing a Bernoulli distribution therefore means choosing a point on a line segment.
So Δn is the space of all possible probability distributions on an n-element set. The small cases are easy to picture: Δ2 is a line segment, Δ3 a filled triangle (two-dimensional, but embedded in R3), Δ4 a filled tetrahedron. In general Δn is an (n−1)-dimensional object with n vertices, called a simplex. One dimension is always lost, because the entries have to add up to 1 – exactly what we exploited for the Bernoulli distribution, where two numbers became one.
The simplest form data can take is a single number, or a sequence of N numbers. We like to call that an N-dimensional vector, or picture it as the column of a table;
in statistics it is a sample of size N. Later we will also deal with tables of more than one column, where the data come as more complicated rows, but for now we stay in the simpler one-dimensional setting.
Even a single such column carries a probability distribution with it, with no modelling assumption at all: we simply count how often each value occurs.
That this really is a probability measure is just the statement that the relative frequencies add up to 1.
If the values are coded as numbers 0,1,2,…, you get this vector in a single line: np.bincount(data) / len(data) (see Numpy, section Probability vectors).
The following example is the special case Ω={0,1}, in which a single number fixes the whole distribution.
With that, every role in statistics has been cast, even if we will not need the names until later: the coin, which could be tossed as often as you like, is the population; the N tosses are a sample from it; and π^ is a statement about the population, obtained from the sample. In the same way a bag of sweets is the population and a handful from it the sample, from which you estimate the distribution of colours in the bag. What you know or suspect before you reach in (the coin looks normal, the bag is a standard mix) will later be called the prior. That the inference from sample to population is never certain, and how to put a number on that uncertainty, is the subject of the chapters Expected value and variance (Chebyshev’s inequality) and Statistical tests.
The distribution of the data is not yet a model – it is only another way of writing the data down. A model only arises once an assumption is added. Suppose the colour dataset above has gained a fifth entry:
i
1
2
3
4
5
xi
blue
red
blue
green
blue
The distribution of the data is now (53,51,51). If, however, we assume that the colours are equally frequent except for one that occurs twice as often, we choose as our model the distribution p=(21,41,41) – even though the observed relative frequencies differ from it. A distribution chosen in this way is called a model distribution. As a rule it has fewer parameters than the dataset has entries, it is smoother, and it says something even about values that do not occur in the data at all.
A model works in both directions. Determining a model distribution from data is the estimation problem the chapter Statistical models and estimators is about. In the other direction, you can draw from a model distribution and obtain synthetic data: a dataset that looks like a real one but is not. Synthetic data are the standard tool for testing a method of analysis, because here you know the right answer and can check whether the method finds it.
We now have two distributions on the same Ω: that of the data and that of the model. The next question is that of the quality of the model – do the data look as though they had been drawn from it? One asks how likely is that?, and the number that answers the question is called the likelihood: the probability of seeing exactly the observed data if the model is correct. A model that makes this number as large as possible is the best one by the maximum likelihood principle; the principle runs through the rest of the course and gets a section of its own in the chapter Statistical models and estimators. It is not the only way to put a number on the difference between two distributions: the chapter Expected value and variance measures the distance between data and synthetic data directly in the data space, and the chapter Relative entropy measures it between the distributions themselves.
That marks out the path the rest of the course takes, and it is the path of Figure 2: choose a section of the world, collect data, clean them (Data cleaning) and translate them into usable features, build models from those, and measure the models against the data. Everything else is the working out of these five steps. The next chapter begins with the last of them: comparing data and model in a single number.