At the end of the previous chapter two distributions stood side by side: the distribution of the data and the model distribution. The question now facing us is how to capture their difference in a single number. The exact answer is the relative entropy, and we are saving that for a later chapter. But there is a much more direct route: instead of comparing the distributions, we compare the data themselves with what the model predicts – the real data against synthetic data, in data space, point by point. That is the route this chapter takes, and because it means taking distances between numbers, from here on we work with real-valued data.
Given two vectors v,w∈Rn (think of v as our data and w as what we expect),
the natural quantity to look at is the mean deviation ∑i=1nnvi−wi.
The trouble with it is that positive and negative deviations cancel each other out.
and the factor n1 in the definition is exactly what makes mae independent of the length of the vector: d1 grows with n even when the model is no worse, mae does not. Since comparing is almost always what we are after, we almost always take the mean. (On the role of the various norms, see also the remark on L0, L1 and L2 in the chapter Descriptive statistics, as well as L1 and L2 regularisation in the chapter Regression analysis.)
The obvious next question, for a given vector v, is which vector w has the smallest mean absolute error. Without further conditions on w, though, the answer is immediate: w=v. We will come back to this question later; for now we content ourselves with asking which c∈R minimises mae(v,c). Graphically: put the numbers from 1 to n on the x-axis and plot the values vi above them. A choice of c∈R is then a horizontal line, and we are asking which such line has the smallest combined distance to all the points.
So the median is defined as a number c∈R at which mae(v,c) is minimal.
That is, for all c we have mae(v,c)≥mae(v,median(v)).
Careful: defined this way, several numbers can be “the” median. That is not a bug, it is a feature.
This definition may be unfamiliar, but it has the following property:
Since the second summand does not depend on c, it plays no part in finding the minimum.
Applying this inductively, all that remains is to determine mae(v,c) for vectors of length 1 and 2.
We have mae((v1),c)=∣v1−c∣, which is minimal for c=v1,
and mae((v1,v2),c)=2v2−v1, which is minimal for every c between v1 and v2. So the median of a sorted list depends only on the middle value, or on the two middle values. The usual definition settles the latter case by choosing median((v1,v2))=2v1+v2, and that is what we will do from here on.
Convince yourself that for every c with a≤c≤b the mean distance to (a,b) is 2b−a, so the vector v=(a,b) has many medians.
The median, then, reflects the data rather poorly – it is completely independent of most of them! – so we need a better measure.
Idea: square the individual error terms in the sum, so that large errors contribute a larger share of it. Conveniently, squaring also spares us the absolute value: it takes care of the sign by itself.
Compared with mae, the mse comes in the square of the unit – for heights in centimetres that is square centimetres, which is hard to interpret. So the square root is usually taken at the end; for the constant model w=mean(v) that gives the sample standard deviation of the next subsection.
For computation the definition is awkward: you first have to determine the mean and then go over all the entries a second time. The following rearrangement needs only the sum of the entries and the sum of their squares:
This view carries further than it first appears. In the chapter Covariance and dependence it will turn out that the covariance of two random variables behaves exactly like an inner product – the variance is then the special case “vector with itself”, and the correlation coefficient is the cosine of the angle between two centred vectors.
Whether a vector v∈Rn carries information for us depends on how much we already know about v.
If we know, for example, that v is a sample of a random variable uniformly distributed on {0,1}, we will not be surprised when v looks like one. Every entry of v corresponds to exactly one bit of information. Suppose instead that the random variable is not uniform but follows, on the numbers {1,…,26}, the frequency of the letters of the German language, say (with 1 for “a”, 26 for “z” and so on). Then an entry of v potentially carries less information. The “e” is so frequent that we are hardly surprised to see one. An “x”, on the other hand, would surprise us a great deal – but then it does not come up very often either. The average information content is therefore lower than for a uniform distribution.
So far we have computed with samples: mean(v) is a number that comes from n concrete measurements. Now we reverse the point of view and ask which number belongs to a distribution, that is, to the model the data might have come from. The route there is short, and it explains why the expected value looks exactly the way it does.
Let X be a random variable with finitely many values y1,…,yk and distribution p=(p1,…,pk), so pj=P(X=yj). Suppose for a moment that the pj are rational numbers with a common denominator N, say pj=Naj with a1+⋯+ak=N. Then there is a sample of size N that hits this distribution exactly: the one in which the value yj occurs precisely aj times. We call it the idealised sampleD~ for p – the sample you would get if chance kept to the probabilities perfectly, just once.
We can write down the mean of this idealised sample directly, since we know how often each value occurs:
On the right there is no sample any more, only the distribution. With that, the assumption that the pj are rational has become superfluous too: the right-hand side makes sense for every distribution, and the detour through D~ served only to find the formula. This quantity is exactly what we call the expected value of X.
The special case k=1 is the acid test: a distribution that takes a single value y1 with probability 1 – the Dirac measure δy1 from the chapter The formalism of stochastics – has the idealised sample (y1,…,y1) and so the expected value y1. A constant model and the value it predicts are the same thing. In the language of the previous section: the best constant model for the squared error was the mean of the data – and read as a distribution, a constant model is a Dirac measure.
With that we can set the formula down as a definition. It works word for word when Ω is countably infinite; the finite sum then becomes a series, which need no longer converge.
So the expected value is the mean of the values of X, weighted by the probabilities.
For finite Ω the sum is finite and always exists. If Ω is countably infinite, the sum is a series, and a series need not converge: there are random variables for which no expected value can be determined. An example: on Ω={1,2,3,…}, P({k}):=π2k26 defines a probability measure (because ∑k≥1k21=6π2), and for X(k):=k the series ∑k≥1k⋅π2k26=π26∑k≥1k1 is the harmonic series, which diverges. This random variable has no expected value.
What we can say is this: if X takes only finitely many values, then not only does the expected value exist but so do all the higher moments E(Xk) – they are finite sums, and those always converge. With countably infinitely many values, by contrast, you have to check each time. An example that is more than a mathematical curiosity: in the St Petersburg paradox a coin is tossed until heads first comes up, and if that takes k tosses, 2k euros are paid out. The probability of that is 2−k, so the expected value is ∑k≥12k⋅2−k=∑k≥11=∞. A game with infinite expected value – and yet nobody would pay a high stake to play it.
For continuous random variables, which take uncountably many values, an integral over a density f takes the place of the sum: E(X)=∫xf(x)dx. We give this definition in the chapter Continuous distributions, once we know about densities. Everything we establish about the expected value in this chapter holds for continuous random variables in just the same way, with integrals in place of sums.
The expected value and the samples of a random variable are intimately connected:
P-almost sure convergence also implies convergence in probability:
limn→∞P(∣Xn∗∣≥ϵ)=limn→∞P(∣Xn−EX∣≥ϵ)=0 for every ϵ>0.
In what follows we shall not rack our brains any further over the notions of convergence in stochastics (that can always be caught up on later, and depending on the application it is worth doing). Instead, in the usual tradition, we take with us the reassurance that the expected value is a suitable quantity for analysing a sample expectantly. The larger the sample, the smaller the deviation of the sample mean from the expected value should be – so the law would have it. Put the other way round: for every prescribed bound ϵ>0 there is a sample size n such that the sample mean of a randomly drawn sample almost always deviates from the expected value by less than ϵ.
That closes the circle back to the idealised sample at the start of the section: there we pretended that a sample kept to the probabilities exactly, just to arrive at the formula at all. The law of large numbers says that real samples do so arbitrarily well for large n – so the detour was no detour.
We have not yet explained what independent means (independently of the pmfs in the discrete case); that comes further down.
This is the counterpart of the shortcut formula rmse(v)2=mean(v2)−mean(v)2 for samples above.
For a centred random variable, one with E(X)=0, this simply gives V(X)=E(X2).
The variance helps us judge how probable a given deviation from the expected value is. The key is an inequality that, to begin with, uses only the expected value:
Markov’s inequality is crude, but it immediately yields the inequality we actually want:
The special case c=σ is trivial: the right-hand side is just 1, and every probability is ≤1.
The special case c=kσ with k∈N, however, simplifies to
So deviations of 2σ have probability ≤41, and deviations of 3σ only ≤91. Measured in multiples of σ, then, the probability of a deviation that large is roughly inversely proportional to the square – which is just what the inequality above says. That also gives us a criterion for weeding faulty data points out of a dataset: if deviations larger than kσ with k>1 turn up more often than expected, then those data points at least do not belong to the distribution we expect.
The most important application of the inequality is to the sample mean itself. With it we can actually prove the law of large numbers from above, in a weaker form and with exactly the tools we now have:
This is exactly the convergence in probability that we deduced above from the (unproved) strong law of large numbers: the weak law is the form we can prove with the means at hand; the strong law, with its almost sure convergence, needs more machinery but does without the assumption of finite variance.
The weak law is also the law of large numbers with a number attached: the probability of a deviation by more than c falls like 1/n – or, read differently, the typical error of the sample mean shrinks like 1/n. To halve the error you need four times the sample. The bound is crude; the chapter The normal distribution supplies a sharper one with the central limit theorem, and the chapter Statistical tests turns that into the recipe for inferring from sample to population.
Applying the law of large numbers to the random variable (X−E(X))2 shows that the sample standard deviation converges to the standard deviation as well. So the sample standard deviation is a good substitute when the true variance of the random variable cannot be determined.
The next section computes with logarithms throughout. Since school may be a while ago, here is what you need, in half a page.
The logarithm counts orders of magnitude. To base 10 you can read that off directly: log10(100)=2 and log10(1000)=3, and because the logarithm is strictly increasing, log10(y) lies between 2 and 3 for every number y between 100 and 1000. The number of decimal digits of a natural number y is therefore ⌊log10(y)⌋+1 – and to base 2, likewise, the number of binary digits.
The rules of calculation all follow from eln(y)=y and ln(ex)=x together with the power law (eu)v=euv:
The last line is the change-of-base formula: logarithms to different bases differ only by a constant factor. That is why the choice of base for the entropy is a question of units, not of substance – to base 2 you measure in bits, to base e in nats, and the two differ by the factor ln(2)≈0.693.
In numpy the three functions are called np.log (natural, not common – a frequent source of errors), np.log2 and np.log10.
Claude Shannon (1916–2001) carried the notion from physics into communications engineering in his 1948 paper A Mathematical Theory of CommunicationShannon (1948), with which information theory began as a field of its own. Shannon asked how many bits are needed, at the very least, to transmit a message, and found the same quantity Boltzmann had written down for gas particles. In his honour it is also called the Shannon entropy.
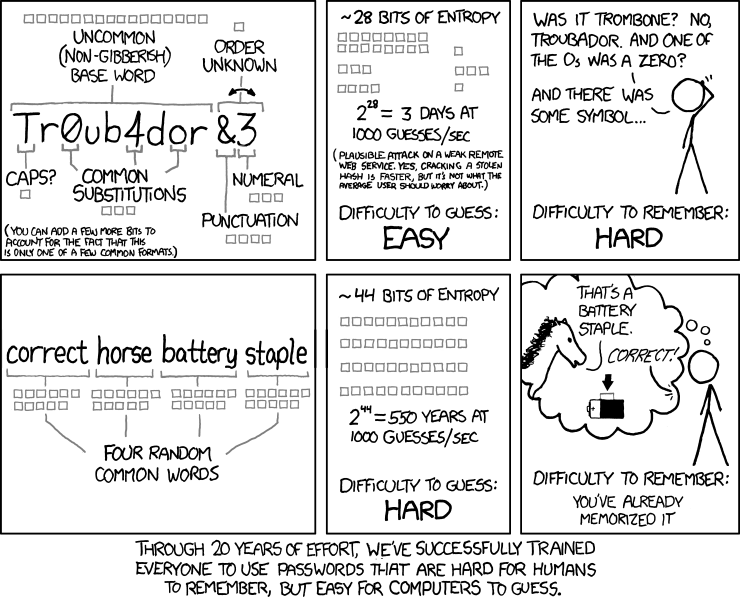
This very argument is at the heart of one of the best-known comics on security:
The password Tr0ub4dor&3 looks complicated, but it was built by a procedure an attacker knows (a word, a few of the usual substitutions, a digit, a special character) – it carries around 28 bits. Four randomly chosen words such as correct horse battery staple carry around 44 bits, so they are about 216≈65,000 times harder to guess – and easier to remember into the bargain.
The lesson is the same as in the previous example: entropy depends not on how the outcome looks but on the procedure that produced it. A password is secure not because it looks cryptic but because the set of passwords it could have come from is large. That is why the question “how strong is this password?” strictly speaking has no answer for a single password – what can be answered is how strong the procedure is.
At the other end of the scale stands the Dirac distribution: if P({ξ})=1 for a single ξ∈Ω
and P({ω})=0 for all the others, then I(ξ)=−log2(1)=0 and hence H(X)=0
(the summands with P({ω})=0 fall under the convention 0log0=0 from above).
That is the smallest possible value, since H(X) is a sum of non-negative terms.
On a finite set Ω, then, we always have 0≤H(X)≤log2∣Ω∣,
with the minimum attained exactly by the Dirac distributions (there are ∣Ω∣ of them, one per element)
and the maximum only by the uniform distribution.
Entropy is best understood as a relative quantity, and that is how we shall treat it later on. In the rest of the course it turns up in two places: in setting up statistical models – the maximum entropy principle in the chapter The normal distribution and the closely related maximum likelihood principle in the chapter Statistical models and estimators – and in assessing how good a model is, where the tools are cross-entropy and relative entropy in the chapter Relative entropy.
In general it makes a real difference whether a family is independent or only pairwise independent, which is why the definition in terms of families matters.
Another notion comes up very often in this connection:
Clearly, for P(B)>0, A and B are independent of each other exactly when P(A∣B)=P(A).
In the sweets example above, P(B∣A)=P(A)P(A∩B)=1/31/6=21, which is not P(B)=31 – that is what dependence looks like in numbers.
Conditional probabilities therefore come up (or rather, become interesting) precisely when two events, or two random variables, are not independent.
The expected value is linear; the variance is not. Instead, the following two rules hold,
and we will need them constantly in the next chapter.
The term E(XY)−E(X)E(Y) that has just vanished is an interesting quantity in its own right:
it is called the covariance of X and Y, and it measures how strongly the two variables are linearly related.
In the chapter Covariance we put it under the microscope and prove the rule once more there,
in its general form, without the assumption of independence.
Rule (2) is why the variance of a sum of independent repetitions of the same experiment
is so easy to compute – we use that in the chapter
The most important discrete distributions
for the binomial distribution.